

PR Newswire · Press release
Supermicro Launches KV Cache Solution with IBM and NVIDIA Demonstrating Significant Inference Performance Benefits
AI summary
Summary by Wenlo · not part of the original release
On November 5, 2026, Super Micro Computer, Inc. announced a new KV cache storage solution created with IBM and NVIDIA. The joint solution integrates Supermicro Petascale storage servers, IBM Storage Scale software, NVIDIA Dynamo inference software, and NVIDIA Spectrum-X Ethernet switches. The company states that testing with a 120-parameter LLM showed up to 56x faster Time-to-First-Token at 130,000-token prompts.
AI summaries can miss details: read the full release below. Not investment advice.
Original release from PR Newswire
As distributed by PR Newswire, unedited.
- The KV (key-value) cache solution integrates Supermicro Petascale storage servers, IBM Storage Scale software, NVIDIA Dynamo inference software, and NVIDIA Spectrum-X Ethernet switches
- Performance testing shows that the KV cache solution reduces Time-to-First-Token (TTFT) for long-context windows compared to systems with no KV cache
- Customers can dramatically improve inference efficiency through higher GPU utilization, throughput, and infrastructure scalability
SAN JOSE, Calif., Nov. 5, 2026 /PRNewswire/ -- Supermicro, Inc. (NASDAQ: SMCI), an AI, Enterprise, Storage, and 5G/Edge Total IT Solution Provider featuring Data Center Building Block Solutions® (DCBBS), today announced a new KV cache storage solution with IBM and NVIDIA. The joint solution integrates Supermicro Petascale all-flash storage servers using AMD EPYC 9005 Series processors ("Turin"), IBM Storage Scale software, along with NVIDIA Dynamo inference framework software and Spectrum-X Ethernet networking.
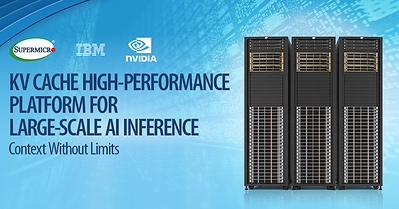
Together, these technologies can dramatically reduce the time it takes AI models to begin generating a response, a critical advantage as enterprises adopt agentic and long-context AI workflows. Extending KV cache capacity beyond local GPU memory can improve GPU utilization and inference throughput, while enabling high availability of KV cache content and non-disruptive scaling of KV cache capacity. The result is a more scalable, resilient inference architecture that delivers faster, more responsive AI experiences.
"As AI workloads expand from training to inference, enterprises and neoclouds deploying high-throughput inference workloads characteristic of agentic AI and long-context, multi-turn generative AI need to remove bottlenecks to improve GPU efficiency," said Charles Liang, president and CEO of Supermicro. "Our solution with IBM and NVIDIA clearly demonstrates these performance benefits."
For a video recap of this release, click here.
Inference workloads consist of two phases: prefill and decode. During prefill, input text is converted into tokens and processed by the LLM to generate the intermediate key-value (KV) states needed for inference. By storing these previously computed KV states in a persistent KV cache, the system can reuse them instead of recomputing the same context for subsequent requests. Agentic workflows, coding assistants, long-context RAG, multimodal AI, and multi-turn applications can generate substantial KV state as they process large codebases, documents, conversations, images, and other context, quickly exceeding GPU and CPU memory and driving the need to offload KV cache to high-capacity, shared network storage.
The KV cache solution from Supermicro, IBM, and NVIDIA provides this persistent storage layer, helping improve inference efficiency, throughput, and scalability while reducing redundant computation.
Key customer benefits of the KV cache solution include:
- Joint Solution Validation – Supermicro, IBM, and NVIDIA conducted extensive cluster-level testing to measure performance, including high concurrency and noisy-neighbor network traffic scenarios.
- Dramatically Faster and More Consistent Inference Performance – In joint testing Supermicro and NVIDIA, with a 120-billion-parameter LLM, persistent KV cache delivered up to 56x faster TTFT at 130,000-token prompts.[1] As input length increased from 30,000 to 130,000 tokens, TTFT increased by only 0.377 seconds with KV cache, compared with 29.55 seconds without it, enabling more consistent performance for long-context workloads.
- Higher GPU Utilization and Throughput – By keeping frequently reused context available outside GPU memory, the solution helps reduce GPU idle time, increase inference throughput, and support greater concurrency without proportionally increasing GPU resources.
- Enterprise Resilience and Trusted AI Operations – A persistent, highly available KV cache helps protect cached inference state while providing shared access across GPU nodes and clusters, supporting more resilient and storage-efficient AI services at scale.
- Validated, Turnkey AI Infrastructure – Supermicro, IBM, and NVIDIA jointly validated the integrated architecture across high-concurrency and noisy-neighbor scenarios, combining NVIDIA Dynamo, IBM Storage Scale software, Supermicro Petascale, servers and NVIDIA Spectrum-X networking.
- Accelerated Deployment Services – Supermicro's factory rack integration and on-site deployment services can reduce the deployment time of this solution from weeks to days.
"Enterprises need a fundamentally better way to scale AI inference. Together, IBM, Supermicro, and NVIDIA are delivering a high-performance, resilient KV cache solution that helps customers maximize their GPU investments, scale independently of compute, and significantly improve infrastructure efficiency," said Sam Werner, GM, IBM Storage. "This collaboration represents an important step toward making enterprise AI inference more scalable, reliable, and cost-effective."
"Agentic AI and long-context applications depend on reusing context efficiently across many steps, and NVIDIA Dynamo helps orchestrate distributed inference so enterprises can get more usable throughput from every GPU," said Shruti Koparkar, NVIDIA AI Inference Product Lead. "By pairing NVIDIA Dynamo and Spectrum-X Ethernet with Supermicro Petascale storage servers and IBM Storage Scale, this KV cache solution creates a high-performance shared storage tier that can reduce redundant computation, improve time-to-first-token and help customers scale resilient AI inference services."
For more information on Supermicro and IBM solutions click here, and to read the IBM Redbook, Context without Limits: A High-Performance KV Cache Platform for Large-Scale AI Inference, click here.
About Super Micro Computer, Inc.
Supermicro (NASDAQ: SMCI) is a global leader in Application-Optimized Total IT Solutions. Founded and operating in San Jose, California, Supermicro is committed to delivering first-to-market innovation for Enterprise, Cloud, AI, and 5G Telco/Edge IT Infrastructure. We are a Total IT Solutions provider with server, AI, storage, IoT, switch systems, software, and support services. Supermicro's motherboard, power, and chassis design expertise further enables our development and production, enabling next-generation innovation from cloud to edge for our global customers. Our products are designed and manufactured in-house (in the US, Taiwan, and the Netherlands), leveraging global operations for scale and efficiency and optimized to improve TCO and reduce environmental impact (Green Computing). The award-winning portfolio of Server Building Block Solutions® allows customers to optimize for their exact workload and application by selecting from a broad family of systems built from our flexible and reusable building blocks that support a comprehensive set of form factors, processors, memory, GPUs, storage, networking, power, and cooling solutions (air-conditioned, free air cooling or liquid cooling).
Supermicro, Server Building Block Solutions, and We Keep IT Green are trademarks and/or registered trademarks of Super Micro Computer, Inc.
All other brands, names, and trademarks are the property of their respective owners.
1Results detailed in IBM Redbook: https://www.redbooks.ibm.com/docs/MD260021/MD260021.html
 View original content to download multimedia:https://www.prnewswire.com/news-releases/supermicro-launches-kv-cache-solution-with-ibm-and-nvidia-demonstrating-significant-inference-performance-benefits-302928472.html
SOURCE Super Micro Computer, Inc.
